
Kimi K3.1 Pro has lower listed base API input and output rates than Claude Opus 5.5. Whether it is the better choice depends on the task: the number of attempts, corrections, and human reviews can matter more than the rate per token.
Both models are being positioned for complex coding and knowledge work. This comparison uses official documentation and published vendor results, rather than an independent hands-on test. The goal is to help you choose a useful evaluation, then make a decision from the work it produces.
API pricing: compare the same kind of usage
For the launch context behind this comparison, see Kimi K3.1 Pro’s new capabilities.
The following US-dollar rates were checked on October 24, 2026:
| Per million tokens | Kimi K3.1 Pro | Claude Opus 5.5 |
|---|---|---|
| Base input | $2 | $4 |
| Base output | $10 | $20 |
| Cache hit/read | $0.20 | $0.20 |
These are API rates. Consumer subscriptions, third-party services, and accelerated modes have separate terms.
Consider a hypothetical request with 100,000 uncached input tokens and 10,000 output tokens. At those base rates, its input and output would cost $0.30 with K3.1 Pro and $0.60 with Opus 5.5. This calculation excludes cache writes, tools, retries, and other charges. It illustrates the rate difference; it is not a measured task cost.
For repeated tasks, record the full bill and the time needed to reach an accepted result. A cheaper request can become a more expensive workflow if it needs extensive correction. A more expensive request has to justify its price through the outcome it delivers.
Coding: look beyond a close benchmark score
Kimi’s release report places K3.1 Pro close to Opus 5.5 on Terminal-Bench 4.0. Those results are evidence about a particular evaluation setup, rather than a guarantee about your repository.
For a useful coding comparison, choose a task with a known failure and a clear acceptance test. Give each model the same project state, issue description, tool access, and time budget. Keep separate copies so one run cannot benefit from the other’s changes.
Inspect three things after each run: whether the issue is resolved, whether unrelated behavior changed, and whether the explanation matches the actual modification. Record any manual intervention. If one model needs a hint halfway through, that intervention belongs in the result.
A small interface repair and a multi-file refactor test different capabilities. Include both only if both represent your workload. A single successful demo is too narrow a basis for moving an entire engineering workflow.
Document analysis: test whether conclusions survive checking
For research work, the comparison should include a question that cannot be answered by summarizing one document. Use a source collection with an outdated figure, a qualified claim, or an apparent disagreement.
Try the same prompt with both models:
Compare the supplied reports. Identify claims that agree, claims that conflict, and claims that cannot be reconciled from the available evidence. Cite the source and location for each. Separate reported facts from your interpretation.
Review the answers without looking at the model labels first. Count unsupported claims and missed qualifications. Check whether either model resolves a disagreement by inventing an explanation.
If you use iWeaver to prepare the source collection, the AI Document Summarizer can help you establish an overview. Keep the actual comparison inputs consistent; giving one model a curated summary and the other raw files creates a different experiment.
When should you evaluate K3.1 Pro first?
Use How to Use Kimi K3.1 Pro to set up a first task and check the result.
Start with K3.1 Pro when the lower listed API rates address a real cost constraint and you have a repeatable task to test. It is also a reasonable candidate when the new release’s coding and research focus matches the work you need done.
Kimi K3.1 Pro is available in iWeaver, and iWeaver provides a free trial of the model. A bounded document task is a practical first evaluation: choose sources you understand, specify the output, and check the consequential claims.
The trial terms do not establish the cost of using Kimi’s API. Evaluate each access route on its own terms.
When should you keep Opus 5.5 in the comparison?
Before paying for accelerated output, review Kimi K3.1 Pro vs. Highspeed to separate speed from task quality.
Keep Opus in the evaluation when you already have a workflow that works well with it. An established process has value: prompts, tools, review habits, and accepted outputs take time to rebuild.
Run K3.1 Pro against a representative sample before switching. Include an ordinary task, a difficult task, and a case your current workflow handles poorly. A new model is most useful when it solves a concrete problem or reduces the cost of an accepted result.
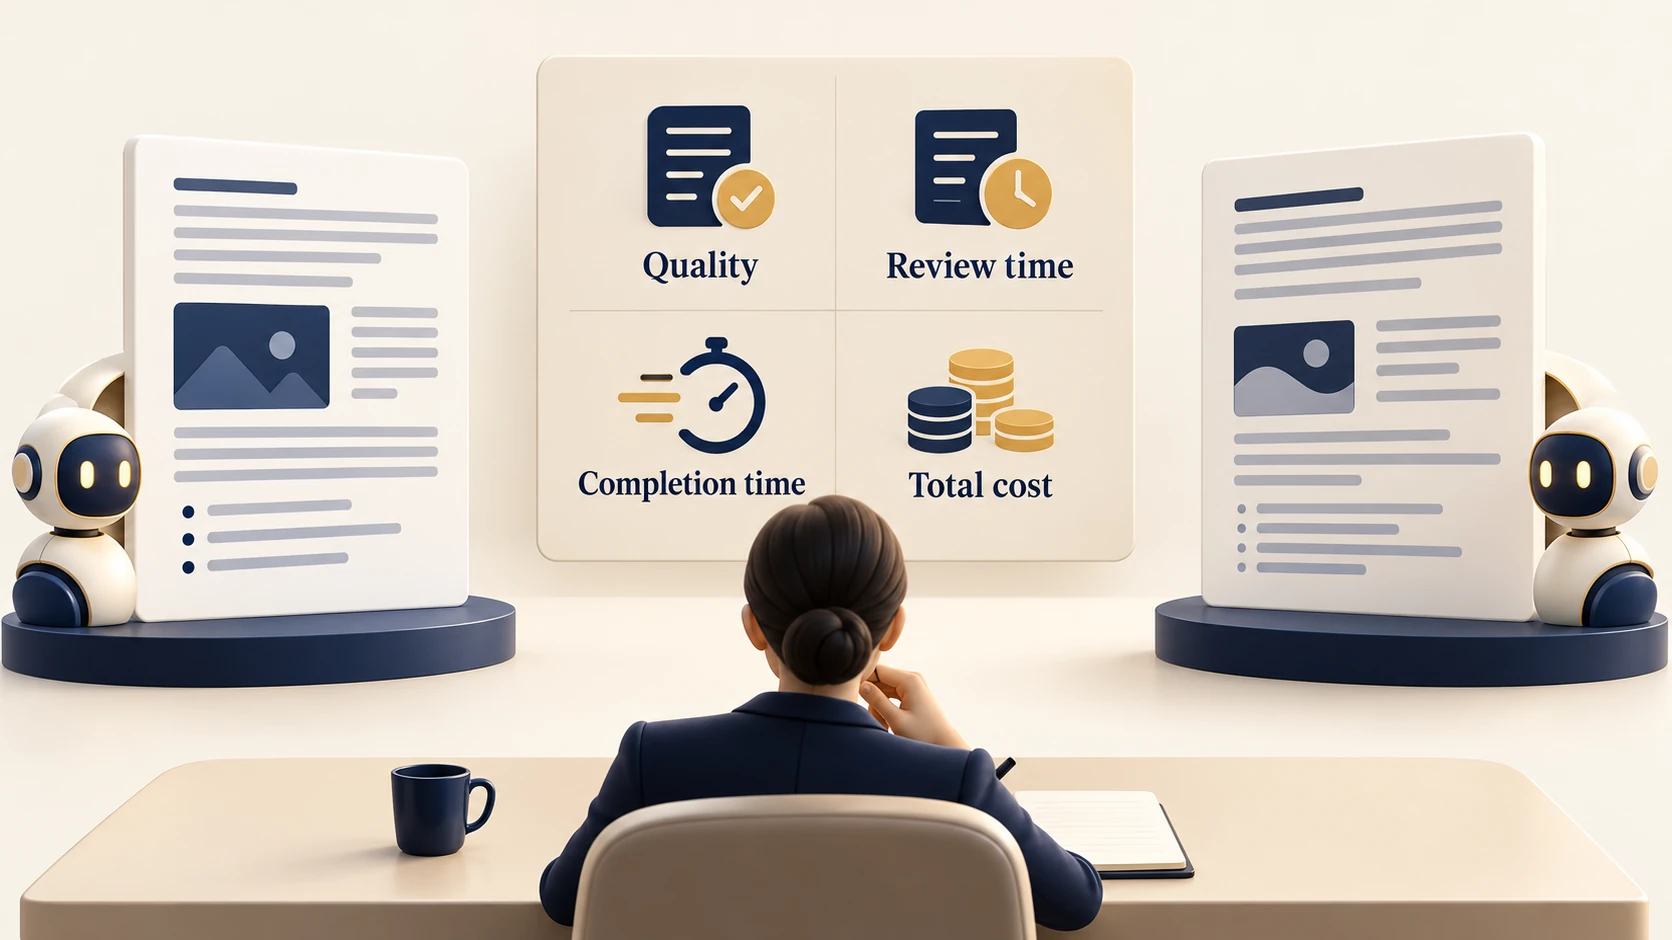
For a final choice, use a simple scorecard: accepted output, correction time, completion time, and total cost. Weight those factors according to the job. A research team may put evidence quality first; a batch-processing system may care more about cost once a minimum quality threshold is met.
There is no need to declare one model the winner across every task. Choose K3.1 Pro where it delivers a better result for your constraints, and retain Opus where your evaluation supports keeping it.